Monday, May 11, 2015

Links for 05-11-2015

How open source is like Yelp--but not really

Open source free culture creative commons culture pioneers

Writing in Venture Beat about Yelp, Chris O’Brien notes:

The problem with this era of companies is that they emerged out of a faulty rationale that gripped the valley for many years. The thinking was, if you just attracted a massive audience first, advertising revenues would inevitably follow.

It worked for Google’s search juggernaut, and eventually it has worked for Facebook. LinkedIn has thrived, for the most part, because it also has a paid pro subscription that means it’s less dependent on advertising. For just about everyone else, though, the notion that if you build it then the business model will come has not panned out.

I generally agree with this analysis. It’s a bit sobering how many household-name social and related companies with tons of users have never really been able to put together a stable, profitable business. And these aren’t flavor of the week companies. Many, like Twitter, own their categories. It would be hard to imagine a web without YouTube which, although it’s been able to monetize some of its content with advertising, is still apparently not profitable. Yet it might not exist had someone like Google not purchased it.

It sometimes seems as if there’s a similar dynamic in open source software—as Dan Woods wrote about last month in “Will there ever be another Red Hat?” VC Peter Levine made related points in 2014 when he wrote that the charging for support on open source bits [1]

model doesn’t work, but its key point of failure is that the business model simply does not enable adequate funding of ongoing investments. The consequence of the model is minimal product differentiation resulting in limited pricing power and corresponding lack of revenue. As shown below, the open source support model generates a fraction of the revenue of other licensing models. For that reason it’s nearly impossible to properly invest in product development, support, or sales the way that companies like Microsoft or Oracle or Amazon can.

This while open source software has become increasingly pervasive. Or, as Simon Phipps writes, the default.

The results from the annual Future Of Open Source survey are in, and they confirm everything we already knew: Open source is now the default.

The survey reports that 78 percent of its respondents are now running their businesses with open source software, and two-thirds are building software for their customers that’s based on open source software. More significant, the percentage of respondents actually participating in open source projects has increased from 50 percent to 64 percent, and 88 percent say they expect to contribute to projects within the next three years.

Making money with open source can indeed be challenging. My employer has arguably had unique success as an organization delivering 100 percent open source products. But, while open source was and is very much about user freedom and enablement, open source has also delivered many benefits to companies creating it even when the it’s not immediately evident as a direct revenue stream. (Leave aside, for our purposes here, companies using open source as part of an open core or Software-as-a-Service approach. That’s a separate long discussion.) 

Consider how open source has vastly decreased the friction around collaborating on software projects between organizations. With development in the open, it’s far easier to work cooperatively without putting a lot of formal processes in place. Open source software also provides a template for contributing and cooperating across silos within organizations as well. Look at some of the key IT trends happening today such as DevOps and the Internet-of-Things. Both require cultures that explicitly value transparency and working across functional boundaries. 

And that’s why open source isn’t ultimately all that much like Yelp and other social sites that have trouble turning a profit. Even those organizations that aren’t “doing open source” increasingly are doing it in fact. Maybe not explicitly, but in the manner that they develop, interact with customers and partners, and operate internally. It’s not just open source software that’s increasingly the default but open source culture.

[1] Peter actually described it as the “Red Hat model” but that’s a significant oversimplification of what the Red Hat subscription model actually means for customers, so I’ve changed the wording for the purposes of this piece.

Friday, May 08, 2015

Forrester Consulting study shows widespread container adoption

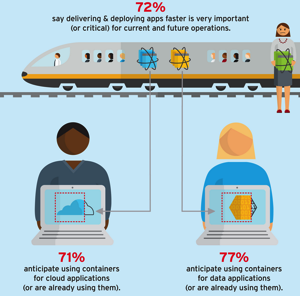
Screen Shot 2015 05 08 at 11 51 16 AM

I find it pretty amazing how both interest in and adoption of containers has gone from essentially zero to 60 over just the past couple years or so. It’s not that containers didn’t exist but they were certainly a niche technology. The rise of cloud infrastructures, tools to manage and orchestrate containers, and an ecosystem that’s bringing things like container certification has changed all that. A new Forrester Consulting Thought Leadership Paper commissioned by Red Hat (reg wall, sorry) brings this sea change home with numbers and recommendations. 

Some highlights:

  • They're being used for many different types of workloads
  • They're being used for a wide range of purposes
  • Adoption should happen strategically with a management ecosystem rather than in silos
  • Adopters should be aware of the benefits of container certification
  • Strategic container adoption is very aligned with DevOps adoption

Containers bring a lot of benefits across a lot of different areas but taking full advantage means avoiding adopting them as an isolated silo and it means taking full advantage of associated tools (such as Kubernetes and Docker) as well as things like container certifications being provided through the ecosystem.

Red Hat has lots more information about containers and our offerings such as Atomic Host on these insight pages. You can also check out an infographic based on the study from which the above image is drawn here.

Tuesday, May 05, 2015

Podcast: The Go language with Red Hat's Mark Lamourine

In this podcast we discuss what features of Go make it so interesting, why compiled languages like Go are a topic of discussion today, and how they fit with containers, microservices, and hyper-scale computing. (And why Mark is porting some perfectly good Python code to Go.)

Links:
Listen to MP3 (0:18:40)
Listen to OGG (0:18:40)

[Transcript]

Gordon Haff:  Hi, everyone. This is Gordon Haff with Red Hat with another edition of Cloudy Chat podcast. I'm joined once again by my colleague, Mark Lamourine.
Today, we're going to talk about the Go Language. This may seem a little different from our other topics around containers, but as you'll see, it's going to come back around to containers just like a lot of things seem to do these days.
Mark, to start off with, one of the interesting trends that we've seen, the RedMonk boys have more or less convinced me with some of their data that we really are seeing an increase in the number of languages that are getting significant deployment these days.
As always, there are a lot of science experiments, but there also seems to be an increase in real, live languages for production use, of which Go is probably one of the most visible candidates.
Mark Lamourine:  Yep and Go, if you look at the origin of Go, it was actually designed with that in mind. In fact, if you look at some of the origin stories, one of the really distinctive characteristics about Go, in contrast to some of the other languages, is that Go is actually designed to make things easier for the computers.
Most computer languages, and it's been my philosophy too, is that computer languages should exist to make programming easy for humans. But, there are a couple of things that they did in the design of Go which were there specifically to make life easier for the computers.
Gordon:  Before we go into that, let's maybe pop up a level for our listeners and talk about where Go fits into the landscape of computer languages which, I think is fair to say, have been dominated by scripting languages over the last decade or so.
Mark:  Yep. That's fairly clear. Most of the big advantages have been in scripting languages. We've certainly got enough CPU power that the arguments against scripting languages for speed no longer apply. Go is in some senses is a step, not backwards, but back towards the machine.
It's intended to replace not scripting languages but C. One of the authors is Rob Pike. He was instrumental in the beginnings of the C language, not the very beginning, but in some of the evolution immediately after and in the early evolution of Unix.
One of his notes was that C is the primary language for system‑level programming, but it hadn't gained any benefit from new understandings of networking, new understandings of distributed systems. The Go language is an attempt to take some of those constructs which didn't exist at all in the 1970s and '80s and build them into a programming language so that they're essentially invisible.
Gordon:  C had also been dragged into doing a lot of tasks almost by default. It was not necessarily designed to originally, and obviously, C++ and a lot of features that came with that where partial attempts to move it beyond being purely a system programming language.
But still, essentially by default given that no other compiled language really took off in the same time frame, C and C++ ended up being used for almost every programming tasks.
Mark:  Pretty much if you weren't scripting it, you were writing it in C or C++. Java is the exception to that. Again, if you're talking about system‑level languages, it's C and C++. Even C++, if you look at the additions that Stroustrup made to C that created C++, he actually started out mostly doing academic experiments on object‑oriented programming.
It turned out later that some of them were useful in wide areas, but they didn't really advance system programming in any way.
In some senses, C++ still is a bag on the side of C. The language constructs are derived from C in ways that other object‑oriented programming languages look cleaner to work with and cleaner to write because they don't have C's baggage with respect to namespaces, and things like that.
Gordon:  Before we get into the container connection, what are some of the innovations from your perspective in Go relative to C and C++?
Mark:  The big ones, a couple of them are controversial...one of them is garbage collection. The single, largest programming error in C programming is memory leaks, is failure to manage memory well.
While garbage collection in compiled languages is controversial, there's definitely something to be said for designing a language that makes it harder to do the most common errors. Java was one of the first attempts to do that.
Java removed pointers completely and said you'll only get references purely because the other really common error was seg faulting due to incorrect memory references or incorrect pointer arithmetic. So, adding language features to counteract user problems, coding difficulties really with the language, has an old history. That's one of them.
The other one which is pretty significant is the library and inclusion mechanism. This was where I was talking about Go being written for computers. One of the characteristics of the C preprocessor is that it re‑reads all those include files. It doesn't know you've read one until you look at an ifdef and say, "Have I already read this?"
You can get situations with nested include files where, I think, in one instance they said they had re‑read the same include files something like 4,000 times to write a fairly simple C program. Go places a restriction on includes that each file can only be included in one place so that when you're building a binary, it knows it only reads that library source code once.
Another innovation which is controversial is that it eliminates the separation of code and headers. In C, you have the code which defines the behavior of some interfaces, and then you have the header files which declare the headers. The point there was to avoid having to reload and recompile all that code.
Go has gone the other direction explicitly. Go has said, "Well, you're going to reload and recompile that code every time, but we're only going to include the things you actually call." The compiler is a bit smarter about what it reads and so they would argue, eliminates the need for the preprocessor.
Gordon:  I said we're going to get to the connection between Go and containers. What is the connection?
Mark:  If you look back at what Google has been doing for their work for the last, at least, a decade. We can't see inside to be sure. They've been using containers, or some kind of container model, for certainly years and possibly as much as a decade.
What they've found in programming their containers among other things is that if you write using scripting languages, you end up having to pull along all of this infrastructure for the scripting language.
You might only have a script that's a few hundred lines long to do a small, tightly‑bound task, but then you have to carry along all of this infrastructure, the binary, the libraries, any special libraries. I'm just talking about the language libraries here, not about the shared libraries that go with the binary.
What they saw in Go, or one of the reasons they designed Go, was to make it so that all those bindings happen at compile time instead of at run time, rather than carrying all of that stuff along to the runtime of the container, if you use a Go binary, those are all resolved at build time.
Your programs, your containers can be much smaller and much tighter. You spend less time pushing around files that you don't actually use. In their mind, Go is a really good language for actually writing container binaries.
Gordon:  One of the interesting things that seemed to have happened here is computers have obviously gotten a lot faster and there's almost been this philosophy, as you said earlier, of it's more important to save the programmers' time than it is to save computer's time, but as we've gone to this hyper‑scale systems, small differences in resource efficiency multiplied by a hundred thousand, multiplied by a million, multiplied by 10 million, starts to look like real resources.
Mark:  What containers are starting to do, is they're starting to expose some entirely understandable laziness on the part of people who are writing scripting languages, writing packaging for traditional operating systems, for conventional operating systems.
When you knew that you were going to be installing this software, you're going to be installing these files, and you knew that once the package was installed on a host, that there were no boundaries between the software that you had installed and whatever application that the user is going to write.
You didn't worry about those boundaries anymore. In fact, we've built up some fairly complex systems that might have usages that run two, or three, or four layers deep. With shared libraries, with scripting libraries, with placement of user‑level libraries, the imposition of containers is starting to expose the fact that there are boundaries there that are being crossed.
I think...over time, as those get exposed, we're going to start looking at things where people are going to go, "We need to be more rigorous, more careful about understanding the boundaries so that we can build tighter, smaller, faster, and more resource‑efficient containers."
Gordon:  This gets to some of the prior discussion we've had in this podcast, around microservices and really understanding what the interactions between different elements are, and that takes some work, but it's really a big win if you do it.
Mark:  And I think that while it's difficult now...because we've understandably neglected it, because it didn't matter on a host, it was a fair assumption that you could reach these things.
I think that as the work happens, it looks hard now...it looks like, "Oh, we've got to do all this extra work." But we got the same kind of response when we first started telling developers, "You can't run that processes as root, or you can't do your development as root." They started going, "How am I ever going to do that?"
Then people modified the Apache stuff so that it would run in its own user space. They modified the packaging itself, so that it would run in its own user space. We've gotten to the point now where people run web servers in their home space and just buy into a high‑numbered port.
This is considered, "What do you need root to do that for?" I think the same kind of evolution is going to happen in containers. As we start understanding these things, they're going to become commonplace and people are going to stop thinking it's all that hard.
Gordon:  One of the things that seems to be happening right now, as computing became more mainstream, as more people were involved, it seems to bring a lot of inertia to certain elements of the infrastructure and ecosystems.
We've talked about languages. C was just too hard to replace because too many people knew it. The virtual machine metaphor in technology which really was what I call the skeuomorphic version of physical servers.
That so many people had invested so much sysadmin learning time in that model, that was hard to displace. Elements of storage and networking infrastructure models, those were hard to displace. But it seems that right now, the whole thing has become so creaky at some level that we're finally getting the energy to replace many of those pieces.
Mark:  I think there are people who were putting their energy into it, because they see a problem that needs to be solved and they've got spare cycles. There are still people who...I saw someone today who said, "What I want is a container image that will run in a container, it will run in a VM, and it will run on bare metal."
And, my response...this is somebody I work with and respect, and he's a really good guy. I looked at him and said, "Why would you ever want that? Because it seems to me you're tossing out the advantages of each of the runtime environments by trying to make all of them one."
I think the characteristics of containers make them suitable for some really cool things. The characteristics of VM make them suitable for slightly different things. The characteristics of bare metal, yet again, we're still going to fight with that inertia, but there is a reason why they're doing it. They need to get their job done quickly and they're following the easiest path.
Luckily, there are other people who see the problem, who see that this is going to be difficult going forward and that we're not taking advantage of the best characteristics of each environment if we continue that way.
And so, we're getting people who are throwing into question the idea that you should treat everything as a VM, or you should treat everything as a container. People are asking the question, which is the most important thing, and they're exploring.
We're going to have some cases where somebody goes, "That looked like a great idea yesterday, but it really bombed." Then, we'll get innovation. We'll get things that are "aha" moments through this...and I think it's exciting that way.
Gordon:  Bryan Cantrill as a side note had quite the rant about running containers within VM at ContainerCamp a couple of weeks back. I'll put the link in the show notes if it's available by then.
Coming back to languages, it's interesting. We're talking about Go here, but Apple has also replaced Objective C in their development tool kit with a new language, Swift.
So it seems that there is this somewhat of a shift away from C in general for at least certain types of new applications.
Mark:  Yes. I think there is a recognition that we had gotten used to the idea that machines were so powerful that you only use C when you absolutely had to be down at the machine level. And that they were tasks that scripting language might not be the best option, but it was certainly the easiest.
There were no resource constraints that would make you turn around and go, "No. I need a system‑level language." Unless there were, in which case you would, but there's a recognition that something between scripting languages and the traditional C system language is beneficial.
That there are places where the overhead of the complete scripting environment is more than you really need and it's worthwhile to try coding something in a compiled language.
Gordon:  Before we close, since we're talking about languages any way, any of the other new language projects out there, anything that catches your eye particularly?
Mark:  You hit on what are the interesting ones to me. They're certainly functional languages that are interesting and there are people who use them in production. It's not something that I follow strongly except as a point of interest.
I think the big thing is going to be the compiled languages. The return to compiled languages, especially in the context of containers, is going to be an interesting phenomenon. It will be interesting to see if people actually do backports.
In one case, I'm working on one where there...there's something I'm working on that requires a full scripting environment, and I'm looking at it, and it requires that because it's intended to run on a complex full host with a completely unknown starting point.
When I try to do the same task if I'm running on a CoreOS box or an Atomic box, I have a much more constrained starting environment. I can make much stronger assumptions about where I'm going to begin.
I'm working now in an environment where pulling in lots of static files just for scripting, it doesn't smell right. It doesn't feel right. I'm actually backporting some well‑written Python code to Go, to see if writing a small, tuned, targeted binary will win over using a more complex script.
Gordon:  In closing, what do you personally really like about programming in Go, just from a purely personal perspective?
Mark:  I hate to admit this but I'm old. I grew up programming C and Fortran. It's refreshing to go back. There are people who I know of are annoyed with the idea that you suddenly have to be aware of INT16, INT32, and typecasting.

I'm remembering my youth. It may not be something that everybody else enjoys, but it's actually fun to get back down and get my hands dirty back at the lower level again.

Wednesday, April 22, 2015

Podcast: Configuration management with Red Hat's James Shubin

James Shubin is a configuration management architect at Red Hat. In this podcast, James talks about the state of configuration management and where it's going. He discusses some of the different approaches among major projects in the (broadly speaking) configuration management space including Puppet, Chef, and Ansible and offers his perspective on how they should be viewed relative to each other.

Links:

Listen to MP3 (0:15:35)
Listen to OGG (0:15:35)

[Transcript]

Gordon Haff:  Hi, everyone. This is Gordon Haff with Red Hat. Welcome to another edition of the "Cloudy Chat Podcast." Today, I'm joined by James Shubin, who writes "The Technical Blog of James, ttboj.wordpress.com." He goes by @purpleidea on Twitter and other places. He's a config management architect at Red Hat.
My guess, we're going to talk about configuration management today. Welcome, James.
James Shubin:  Hi, Gordon. Thanks for having me.
Gordon:  Great to have you here. Let me start off with ‑‑ to set the stage here, from your perspective, what is this config management thing?
James:  Config management. Let me run you through the quick, five‑second basics that I get everyone on the same page so at least we can use the same words. The three separations that I like to make is there is something that is provisioning, there's something that is config management, and then there is something that is orchestration.
Sometimes, we blur the lines. Just to set those straight from day one, provisioning is everything that happens that gets your machine up and running. Basically, a kickstart or a vagrant up or something like that. After that, everything that happens after that is config management. That configures the machine, it might install packages. Lots of things can go on.
After that, sometimes people like to manage things. We typically call that, "Orchestration." When there's some external force that goes and pokes things to do something, that's orchestration. The reason I like to make this clear is because there's lots of great tools out there, and some of them blur the lines of config management and orchestration.
A tool like Puppet is a pure config management tool. Same thing with Chef. There are things like Ansible which are crossing the line between config management and orchestration. It gets everyone a little confused, but those are the terms that we use.
Gordon:  I'm going to dig into a little more detail about the differences between some of the tools out there, and how they overlap and don't overlap. Before we get to that level of detail, from your perspective, what's changing about config management today? What's the interesting stuff that's happening?
James:  A lot of interesting stuff is happening. A lot of config management didn't used to happen in the past. People had a smaller number of machines, there weren't as many services. Now we have microservices, we have more and more machines. As things go on, automation isn't a question of if you do it well, you'll have to do it.
If you're not doing config management, if you're not doing automation, you simply won't be able to run your infrastructure. It's becoming more and more essential. Once upon a time, we would have little bash scripts that glued everything together. Some people still do. CFEngine was an early player that was somewhat popular, although I wasn't a huge CFEngine user, personally.
Newer technologies like Puppet and Chef are quite popular these days. In the future, I think that's going to change, too. The scales are getting bigger. There's a promise that ARM servers could happen and increase host counts by 10 or 100 or maybe more. A lot's changing there. The fact that containers are getting quite popular is definitely going to change the scene a little bit, too.
I don't have the magic glass ball that can tell me exactly what's going to happen. I'm definitely following it closely.
Gordon:  Let's talk about containers specifically. That brings a significant change in the way we operate systems. While you can look at containers as virtualization lite, as I've talked about in some of my previous podcasts, that's not the best way to use containers.
James:  Fair enough. The biggest message around containers that I would like to put out there...I think many of my colleagues and peers in the community agree, especially in the config management community.
While containers are a great technology, and there's definitely a lot of cool stuff happening there, this unfortunately, does not get rid of the need to still do config management. The role might change a little bit, how it glues together might be a little bit different, but it doesn't go away.
If anything, config management needs to be adapted and more flexible, and have new paradigms so that these things work that much better. The current generation of container stuff, containers have existed for ages, but quite recently they're getting quite hot and popular.
A lot of the current generation of config management tools, were written and designed before containers were very mainstream. That might have to change. They might have to make some big changes, and some of them are trying. We'll see how well they succeed. Maybe someone will come up with something entirely new that solves this problem much better.
Gordon:  Another change that's not directly related to containers, although they're part of the same general sea change, is this shift towards VMs or containers or services, that aren't long‑lived, that have a very short lifetime. The pets/cattle thing. One of these things goes bad, you just shoot it and start up a new one. How does that change config management?
James:  You've still got to configure how those things are built, and what goes in them and what settings get set for them. There are tools like Kubernetes that are particularly good at managing these cattle. That'll glue them together with containers.
I have a product, more of a project called "Oh‑My‑Vagrant," which I use to actually test and glue a lot of these technologies together. It's an environment on top of Vagrant, which is a great development tool. It will also glue in Puppet and even Ansible and Docker and Kubernetes and things like that.
If you want to spin up a test environment to test this out for yourself and to make it easy to develop your app, you can do that. I've got some new screencasts coming that I've been publishing on my blog. There's some stuff there now, and some more stuff is coming quite soon.
Gordon:  Let's dive a little deeper into some of the individual products and projects that are out there. What are they good for? Who are they interesting to? How are they evolving? Let's start with Puppet.
James:  Puppet is one of the most popular tools. It has a tricky learning curve for some people. I think it's a useful tool. I've done quite a lot of very complex and advanced Puppet things. I'm grateful that it existed, because it's where I did a lot of my learning about config management from.
The language, the Puppet DSL, the domain‑specific languages, is mostly declarative, which is uncomfortable for some people who are used to more imperative programming tools. Somehow, Puppet folks have made some really, really brilliant features. One of my favorite is exported resources.
It's a feature in Puppet that lets you declare things that seem to be part of one host but get exported, and those definitions get exported and used on a different host. When you're doing multi‑machine things, which I think are interesting. Puppet has some nice patterns that make it more natural.
It's not perfect. There're definitely some problems and missing pieces there, but it definitely has been very inspiring.
Gordon:  Now, the developer, as opposed to the operator or the ops community, Chef is probably the most popular tool today. Right?
James:  I'd like to see more of less developer versus ops and really more ops devs or dev ops, as we sometimes hear on the Internet. Getting those two to converge might be an impossible fight. A lot of places that I've seen people converge the two, and have much more truer DevOps environment, they see a lot of gains.
You can move a lot quicker. You can ship code that you own and are responsible from. You can make changes very quickly. There's a lot of organizations that are literally making changes every minute and every 10 minutes and moving that quickly.
When you can use DevOps techniques to move that quickly, you can innovate a lot quicker than some of the slower‑moving competition out there.
Gordon:  What is it, specifically, about Chef that makes it interesting for developers and the dev ops folks?
James:  I'm not a heavy Chef user. I've used Chef a bit, but not as extensively as Puppet. That's just a personal choice. I know that the Chef community is awesome. Nathan Harvey, one of their community guys, is a really nice guy. Every time you meet him at conferences, it's great. I wouldn't be surprised if one of the main answers is their community.
They have a lot of other great community people. Another thing about Chef is that it's not declarative. Not fully declarative, anyway. There's a lot more imperative Ruby being used. It might be a lot more comfortable for people who aren't familiar with the declarative paradigm. Personally, I think we should get used to the declarative paradigm.
For a lot of people that don't want to dive down that rabbit hole, Chef can be a great step into config management.
Gordon:  You've talked about this declarative versus imperative. Maybe for our listeners, spend a couple of minutes talking about what the differences are?
James:  This has changed a little bit over the lifetime of Puppet, because there are pure declarative languages and stuff. Puppet's maybe not purest. Imperative is what we're typically used to in a programming language. You have for loops and the typical structures you see in Python and Ruby.
The types, which are the things that we declare or state in config management exist. In Puppet, the constructs that set up those types can also be declarative. In pure Puppet, there didn't used to be for loops and things like that. There were classes and things that are called defines. You would set those up. You would have a relatively logical but well‑organized code base.
All of the more complex redefining of variables and little things that can cause programming errors in imperative space don't really exist in this language. It actually makes your code safer. I realize I'm probably explaining this extremely poorly. That's probably because I've got my head stuck in the sand, so deep into code that I forget how to define things.
Hopefully that gives you a good example, and can convince people to look into the specifics and see. If you're writing code that runs on thousands of machines, you could make a mistake. You could make a mistake.
Something like an off‑by‑one error, that could perhaps be prevented quite easily with a declarative language, could blow away a whole bunch of machines or a whole bunch of data. There is a use for safer declarative languages.
Gordon:  One of the ways I think about, and it's probably a bit simplistic, is imperative you're telling something...what to do, and declarative is you're telling it where you want it to end up.
James:  The concept of states and defining what state you want to converge towards exists in all the languages. How you define those state elements can be a bit more dynamic and be programmed a bit more classically in Chef than in Puppet.
Gordon:  One other project we're starting to hear quite a bit more about these days is Ansible.
James:  Ansible is an interesting project, because people lump it into the what's config management space. I don't see it in that space. The easy way you could decide if it's in the same space is is there some cluster, architecture, or infrastructure where you would have more than one of these tools?
If you would use Ansible with Puppet or Chef, would it still make sense? It might not be necessary. What Ansible really does is it's idempotent. What that means is that if you write some code or have some sort of line that says I'd like to do something and you run that over and over again, if it's idempotent it should converge towards that state.
Some operations, like appending to a file, they would not converge. They would diverge, and you would never end up at one, single state. Puppet, and Chef, and Ansible are all idempotent, which means you can run the code as many times, and you should converge towards that one state.
The difference is that Ansible, like I said, isn't purely config management. It's more of an orchestrator. You actually run it on your laptop or on, arbitrarily, one server. It goes out over SSH and applies things, in an idempotent way, to a number of servers. In contrast, Puppet and Chef run on that machine and configure directly.
Gordon:  Any other projects that have particularly interested you in this general space?
James:  Which ones have particularly interested me? There's a lot of little, random things that I look at and poke at. I don't think a lot of them are worth mentioning. I think we'll see some exciting changes over the next three months. I would wait and see what comes up. Nothing I wanted to call out today specifically.
Gordon:  Anything we haven't covered that you think our listeners might be interested in?
James:  There's a lot of stuff going on. I've been doing a lot of config management and containers work lately. The big thing that I'm hacking on at the moment, this week, is Oh‑My‑Vagrant. I definitely encourage you to have a look at that. It's a simple way to make a Vagrant environment without writing a thousand lines of Ruby.
There's some great stuff happening in the systemd‑nspawn world, which I think is quite interesting and I think is a serious technology win. That's quite interesting, if you're interested more in the container space. For config management, I don't know what's going to happen in the future. I have some ideas.

Hopefully, they'll be interesting things that we can talk about in a few months, or in a year down the road.